The Short Version
A vector database answers one question: what is most similar to this query? It returns the nearest embeddings and stops there. SenseLab answers the questions that actually decide whether an agent should act: who learned this, how confident should we be, what happened the last time someone acted on it, which action has worked here before, who else on the team knows it, and can I see the reasoning six months later. And it answers the one that comes after: when acting on it failed, what fixes it? A vector database returns the same vectors next time. SenseLab lowers the confidence of what the run relied on, grades the run, opens an incident when the failure recurs, and replay-tests a fix before it ships. Those are not two flavours of the same product. A similarity index has no notion of an author, a version, an outcome, a judge or a teammate, and no amount of metadata columns adds one. Everything on this page that a vector database does not do is something you would be signing up to build and then maintain. This is not a small gap. In our benchmark — six production-shaped scenarios, two frontier models, about 35,000 agent episodes, with the rules changing under the agent at episode 20 — memory without an outcome loop made the agent worse after the change than no memory at all: it applied the stale fix on twice as many first attempts, with full confidence, because the store kept ranking it first. SenseLab recovered to 0.69 first-attempt success on the changed tasks, where Mem0 sat at 0.40 and no memory at 0.31. SenseLab vs Memory has the numbers.Side-by-Side Comparison
What Vector Databases Don’t Do
Vector databases are stateless retrieval indexes. They don’t track:- Who wrote the data — No provenance. You don’t know which agent or process created an entry.
- How trust evolves — No confidence scoring. A vector’s relevance score is similarity to a query, not a measure of whether acting on the information has ever worked.
- What happened when you used it — No outcome tracking. If an agent retrieves a vector and acts on it, and that action causes an incident, the vector database has no way to learn from that.
- What to do about a failure — No judge, no incident, no fix. The run that went wrong leaves no mark, and the same result comes back next time.
- Which action to pick — No record of what worked here before, so every run chooses from scratch.
- How data changed over time — Vectors are overwritten or appended. You can’t ask “what did this entry say last week?”
- Why a decision was made — No causal chain linking retrieved data to actions and outcomes.
- How to collaborate on changes — No branching, no review process, no way for one agent to propose a change and another to approve it. It’s like coding without Git.
What SenseLab Does Differently
SenseLab is designed for agent learning — the layer between retrieval and action, and the loop that runs after the action:Knowledge has identity
Every entry has anentity_path and key that give it a stable address. Agents read and write to specific keys, not anonymous vectors.
Knowledge has provenance
Every entry records who wrote it, when, and in which session:Knowledge evolves with outcomes
When a run succeeds or fails, every entry it relied on is re-weighed:0.7 drops to about 0.26 on its first failure and lifts to about 0.82 on its first success. A rule validated many times that suddenly fails is flagged as a regime shift, and agents in that scope are steered to try something else.
Knowledge tells the agent what to do
A briefing is compiled per entity — validated learning first, discredited learning set aside — and when the task ends in a choice, the priors say which action has worked here:Knowledge has full history
Every write creates a new version. You can replay the state at any point in time:Decisions are explainable
The causal chain shows exactly what informed a decision — SenseLab entries and external tool context — and the sealed trace behind it keeps the actions taken, the attempts abandoned and every LLM call:Failures get repaired
None of this needs code. Judges grade every run; a failure that recurs becomes a named behavior and opens an incident, segmented by model, agent version and tool; a fix to the learning is staged on a branch, replay-tested against the failing and passing runs, shipped, and verified a week later. A repair policy decides whether fixes wait for review or ship on their own.Behavior
The repair loop in full: judges, behaviors, incidents, fixes, replay, canary, verify and rollback.
What it costs to build this yourself
Teams rarely set out to build a learning platform. They add a versions table to a vector store, and eighteen months later they own one. Here is what sits between a similarity index and something an agent can safely act on:
Each row is a system, not a sprint. Each one grows edge cases the first production incident finds for you. And none of it is your product — it is the substrate your product needs in order to stop repeating itself.
SenseLab is that substrate, already built, already carrying other teams’ traffic.
You probably do not need a second database
The usual reason to keep a vector store alongside a memory layer is search. SenseLab does that itself:- Hybrid search — full-text, semantic similarity, recency and confidence, combined into one ranked result rather than a similarity score you then have to re-rank by hand. Ranking is learned from your outcomes, so what worked here ranks above what merely matched.
- Documents, chunked and embedded in place — upload a document to a room and SenseLab splits it on sentence boundaries with overlap, sizes each chunk to the embedding model’s real token budget, and makes it searchable alongside everything the team has learned, with page numbers in the results. No second pipeline, no second copy, no sync job between them.
- A knowledge graph you did not have to build — entity relationships and causal links materialize from normal reads, writes and outcomes, surfacing connections similarity search cannot.
The Compounding Loop
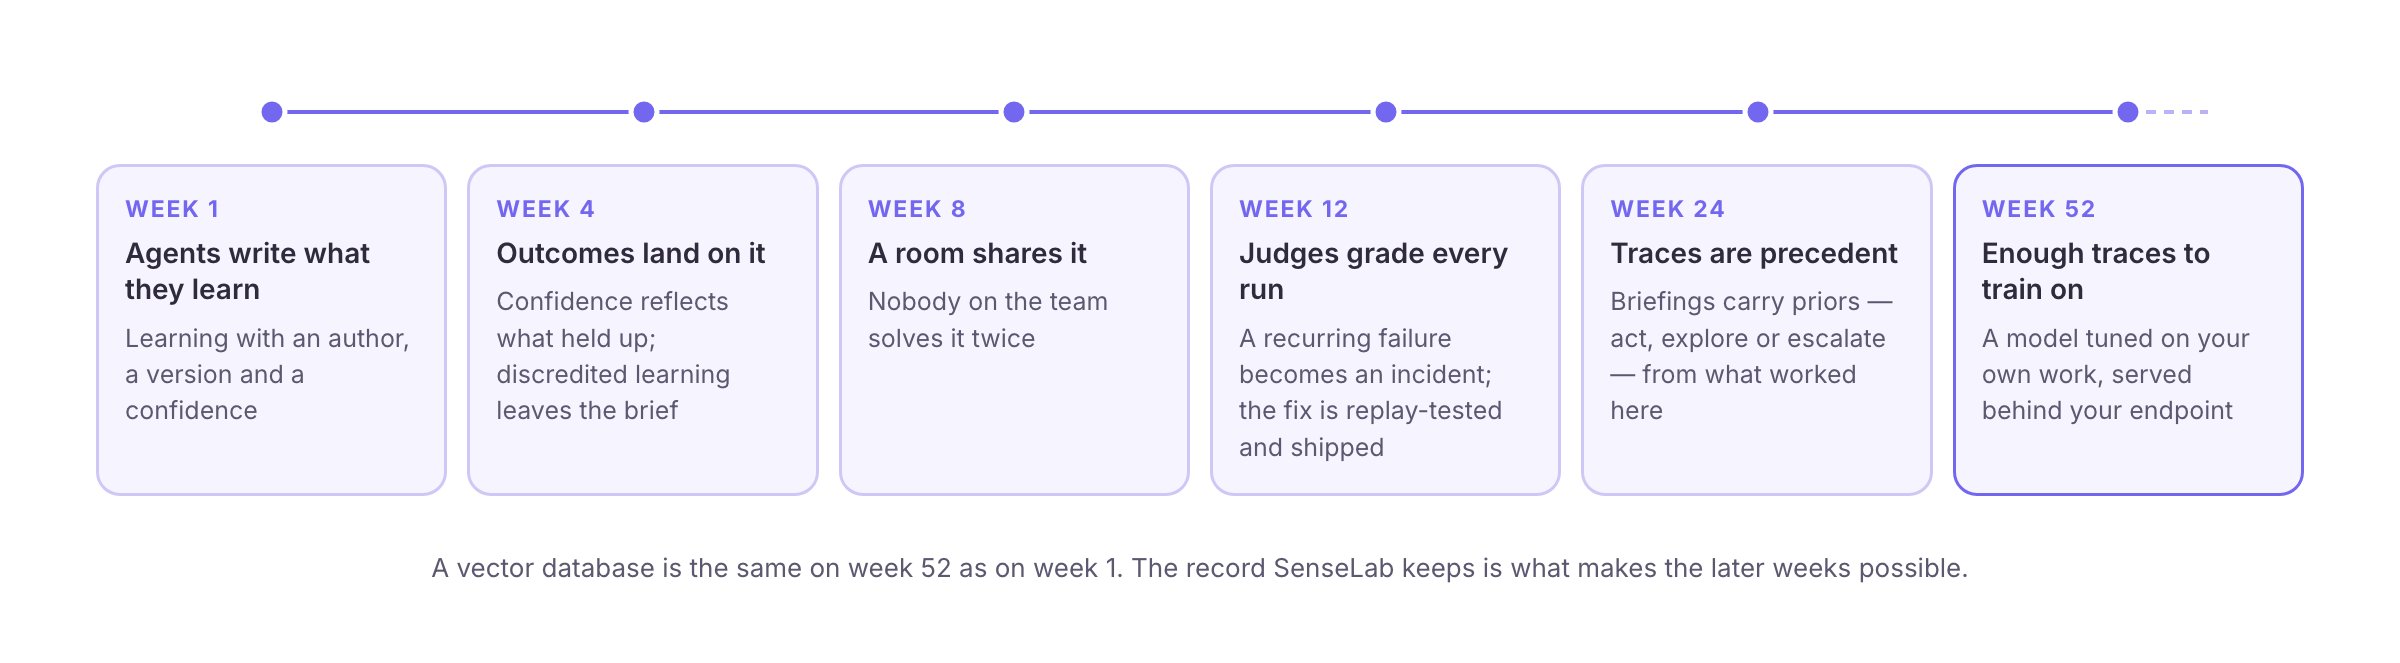
The fundamental difference becomes clear over time. A vector database stores static embeddings that you retrieve. SenseLab builds a compounding record that gets more valuable the longer you use it: