The Problem
AI agents are stateless. Each session starts from scratch with no memory of past decisions, patterns, or mistakes. When something goes wrong, there’s no way to answer:- What information did the agent have when it decided?
- What external sources did it consult, and what did it do?
- Has a similar decision been made before, and what happened?
Decision Traces
A decision trace is a structured record of how an agent turned context into action: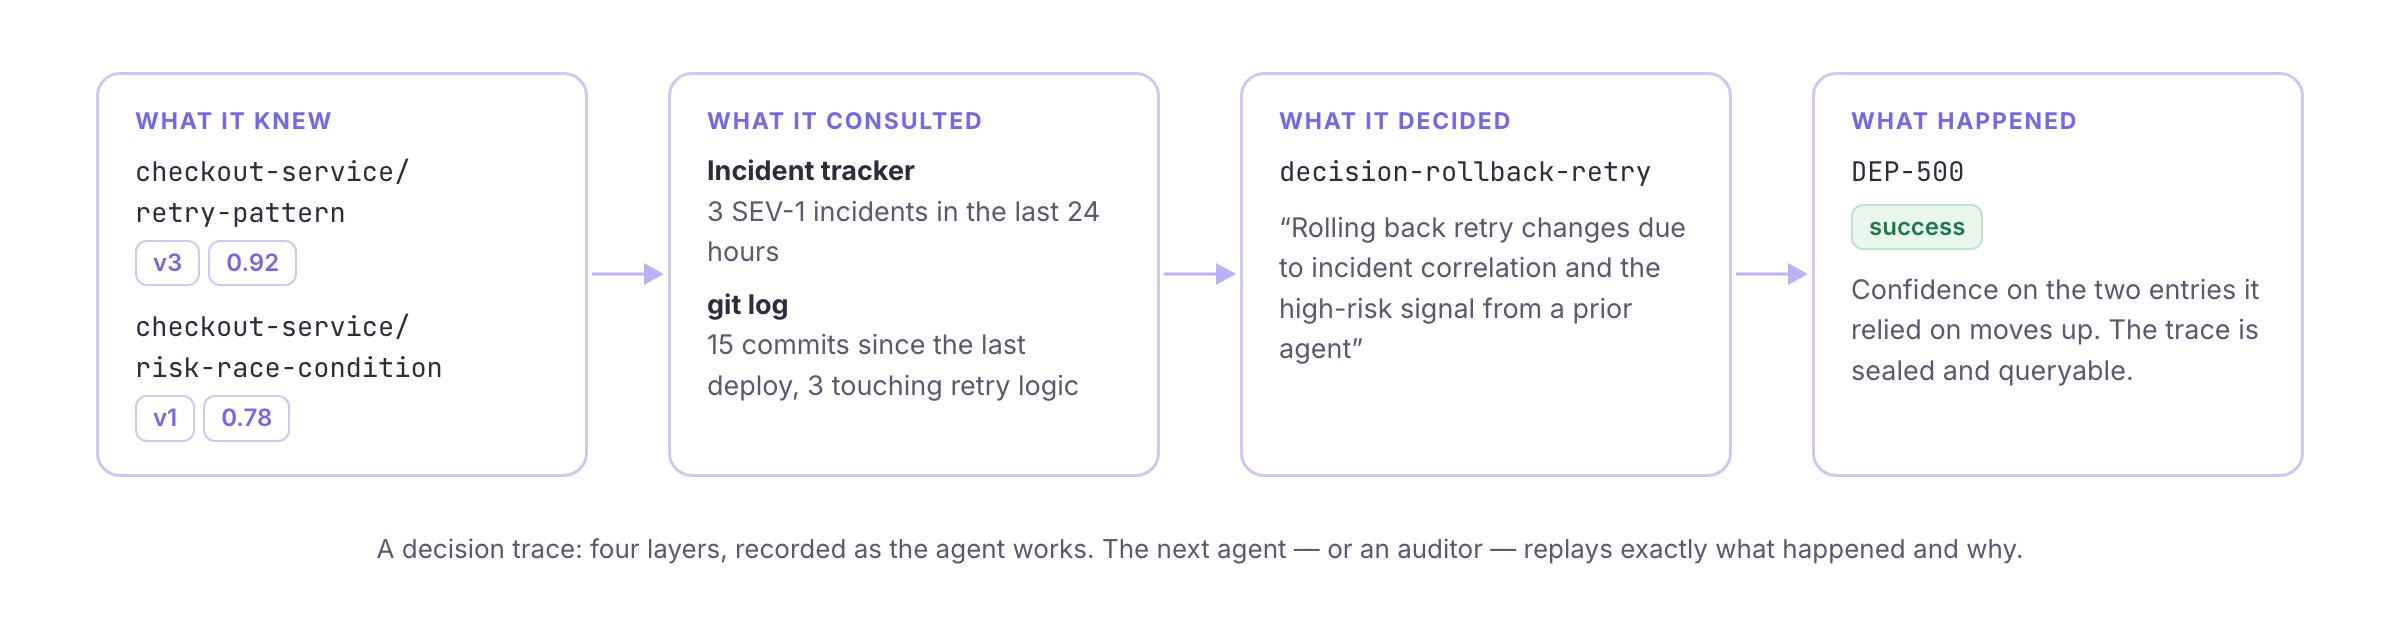
How SenseLab Captures Decision Traces
SenseLab’s existing primitives map directly to each component of a decision trace:1. What the agent knew
Everyread() call is automatically logged by the ReadTracker. When the agent later commits an outcome, SenseLab knows exactly which entries informed the decision.
2. What external inputs were gathered
record_context() captures tool calls, API responses, and other external inputs without writing to storage. These appear in the causal chain alongside SenseLab reads.
3. What the agent decided
The agent’s decision is written as a versioned, provenanced entry:4. What the agent did
Consequential actions — deploys, rollbacks, edits, refunds — are recorded as they happen, failures included. When a remembered approach did not work, the attempt is closed before the next one starts, so the entries behind it receive the failure rather than the credit for the recovery:5. What happened next
The outcome closes the loop. Confidence moves on the causal entries, and the request and the answer travel with the trace so a judge can grade the run later:6. Why did we do that?
explain() returns the complete causal chain:
From Traces to Graphs
Individual decision traces accumulate into a context graph: entities connected by decision events with “why” links.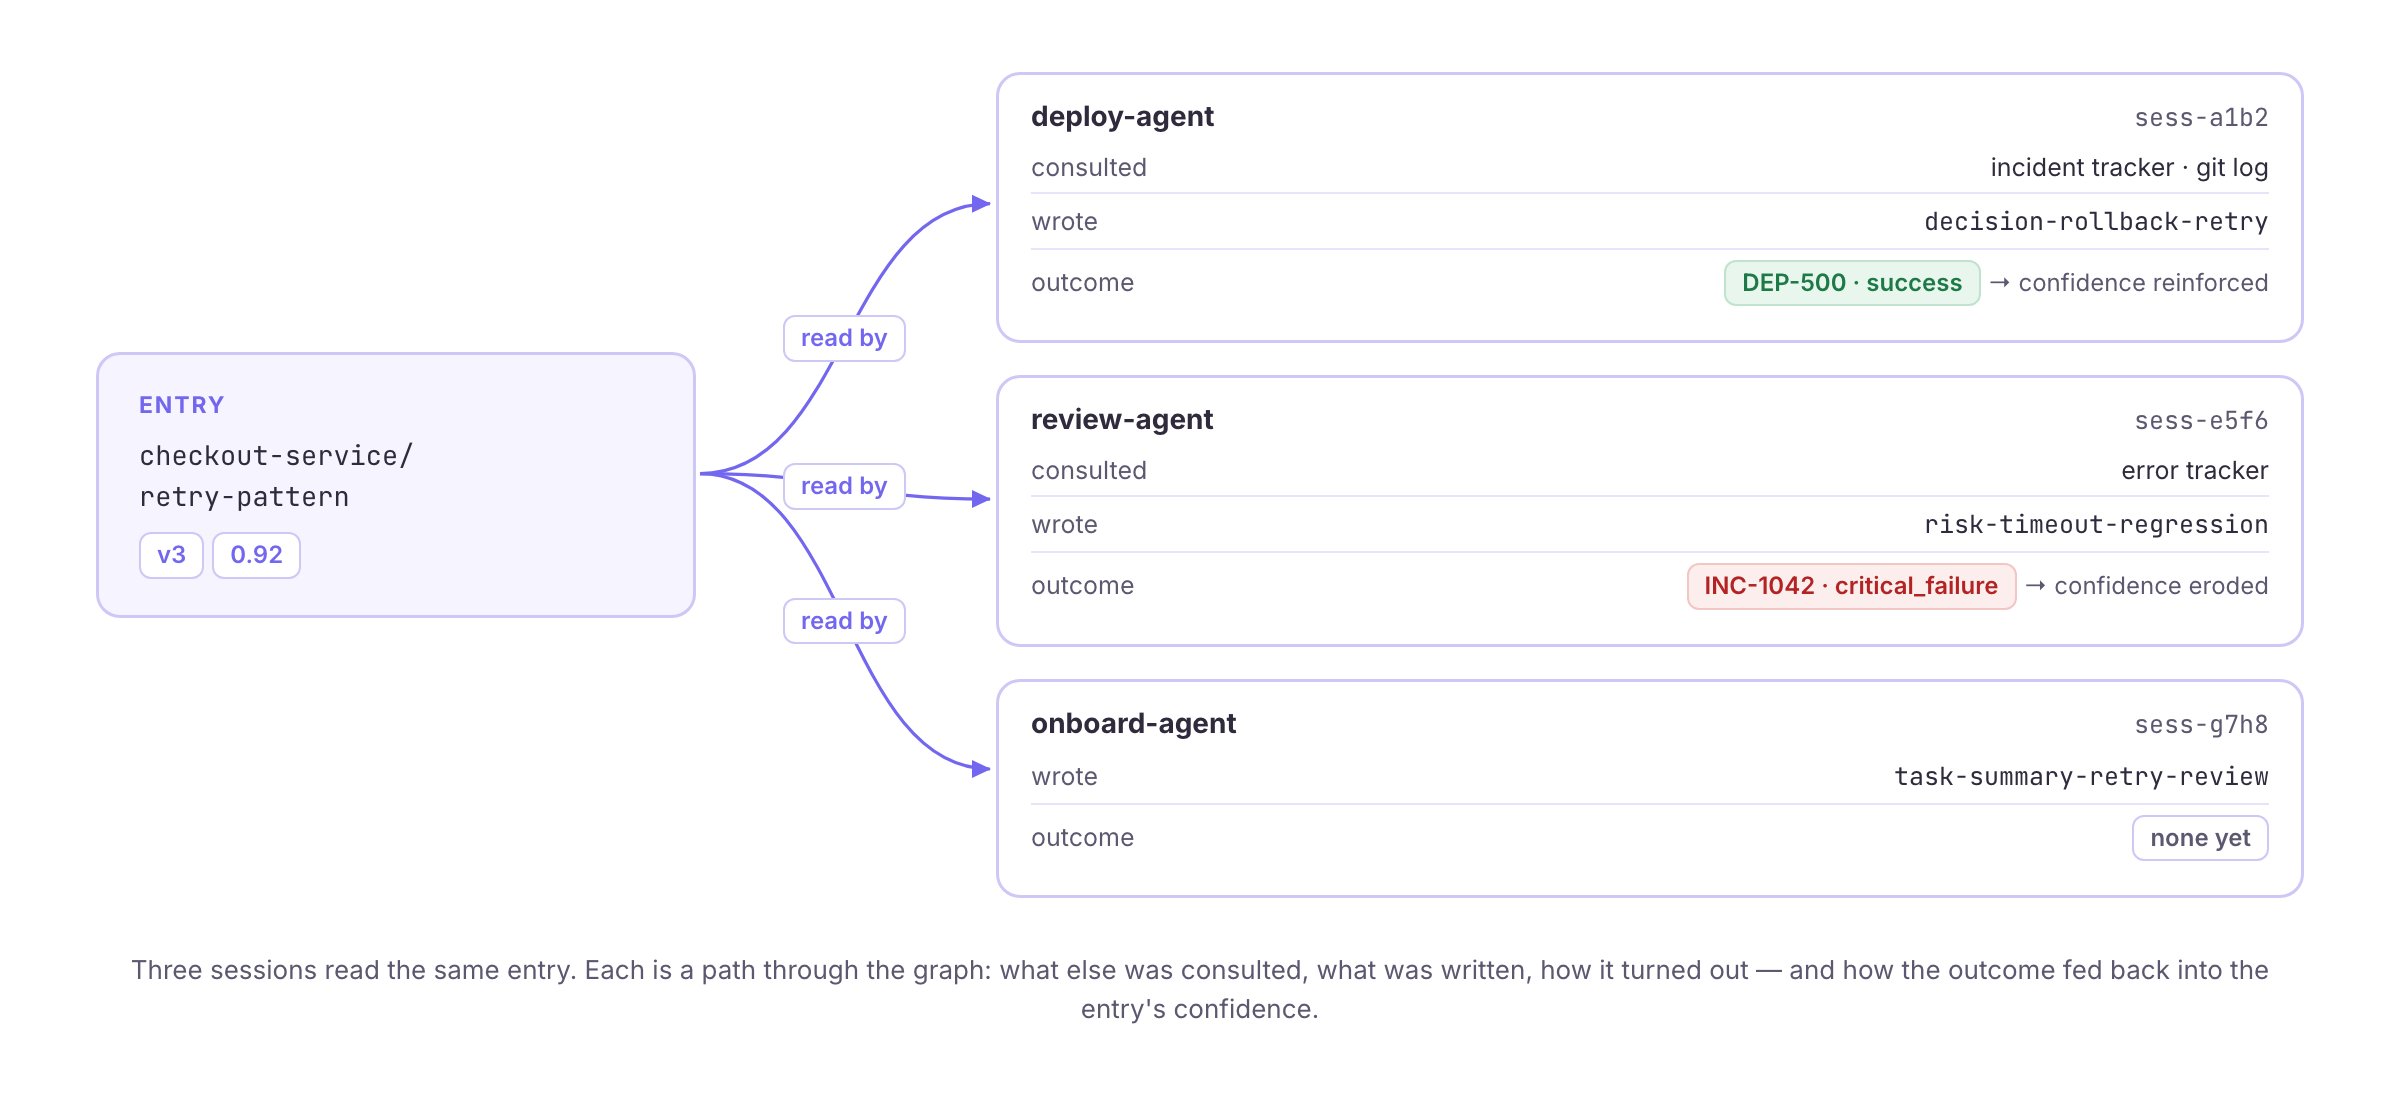
- Precedent — “The last time we saw this pattern, we rolled back and it worked.”
- Exception logic — “We always check for open incidents before deploying changes to retry logic.”
- Cross-system synthesis — “The decision combined SenseLab memory, open incidents, and git history.”
The Knowledge Graph
A persisted knowledge graph complements the session-scoped decision trace. The two layers serve different purposes:
Both layers are always on — the graph materializes from normal reads and writes,
and traces are recorded as agents work. Neither needs to be enabled or
configured.
How Edges Are Created
The knowledge graph is populated automatically — no manual graph construction needed:
Each edge carries
confidence, evidence_count, first_seen, and last_seen. Repeated materializations increment the evidence count rather than creating duplicate edges.
Querying the Graph
Agents can explore the knowledge graph via the SDK or MCP:CONNECTION_MAP digests from graph edges, surfacing the most important relationships for an entity during amfs_briefing().
The Feedback Loop
Decision traces compound through SenseLab’s outcome system: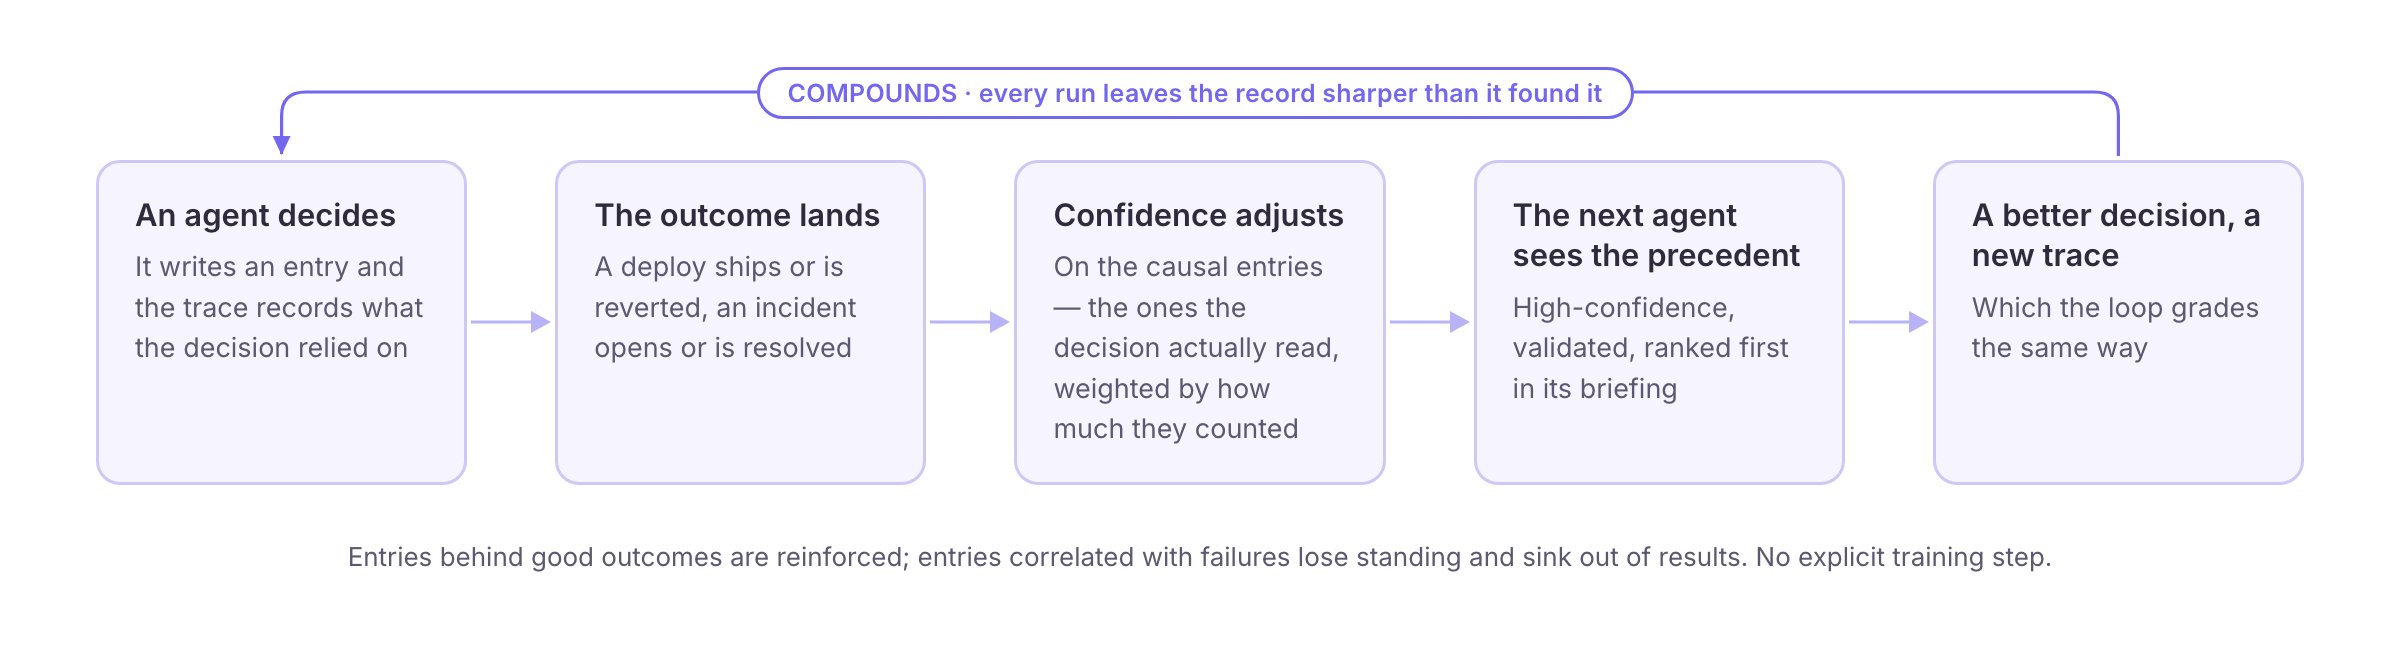
Enriched Decision Traces
Whencommit_outcome() is called, SenseLab automatically captures a rich snapshot of the session:
Per-Agent Memory Graph
SenseLab tracks which agents interact with which entities, enabling per-agent memory views:Immutability and Replay
Because SenseLab uses Copy-on-Write versioning, decision traces are immutable. You can reconstruct the exact state of the world at any past decision point:Immutable Decision Trace Store
SenseLab extends the traces in SenseLab Open Source with cryptographic guarantees and advanced telemetry:- HMAC-SHA256 signing — every trace is signed with
content_hashand chained to the previous trace viaparent_hash, forming a Merkle chain that detects tampering - LLM call spans — record model, provider, prompt/completion tokens, cost, latency, temperature, and finish reason for every LLM call during a session
- Write events, tool calls, agent interactions — full audit trail of every action
- OpenTelemetry export — export traces as OTel spans following GenAI semantic conventions, compatible with Jaeger, Grafana Tempo, Datadog, and Honeycomb
- Auto entity extraction — LLM-powered extraction of entities (services, people, tools) and relationships (depends_on, uses, manages) from trace data
- Immutability enforcement — updates and deletes are blocked at the storage layer, so a sealed trace cannot be edited or removed even by an administrator